On-device dictation for macOS
Dictation that never leaves your Mac.
One key, your voice, text at the cursor. Recognition runs on this Mac and nothing is uploaded. No account, no telemetry, nothing to switch off.
Apple Silicon, macOS 14 or later.
$39 once. 30 days to change your mind.
Move the review to Thursday and keep the budget line as is
Pasted at the cursor. One undo removes the whole dictation.
The audio never leaves the Mac.
-
01
The audio stays here
Recognition runs on the Mac. There is no server to send your voice to and no account to attach it to. The app ships with no analytics, no telemetry, and no crash reporter that phones home with what you said.
-
02
Tested on your voice
A short first-run recording scores every model installed on this Mac against your own voice, in your own room, then picks the winner. The scores stay on screen, so the choice is something you can read instead of something you have to believe.
-
03
Paid once, not rented
$39, one time. No subscription, no monthly word limit, and no upgrade tier standing between you and the model you already downloaded. If it does not earn the $39, you get the $39 back.
Two ways to run dictation. Only one of them keeps the audio.
Cloud dictation sends your speech to someone else's computer. That machine can be subpoenaed, breached, or misconfigured — and you will never know which happened.
Cloud dictation
Your audio crosses the internet to a server you do not own. It is transcribed there, and it is logged or kept somewhere you cannot see.
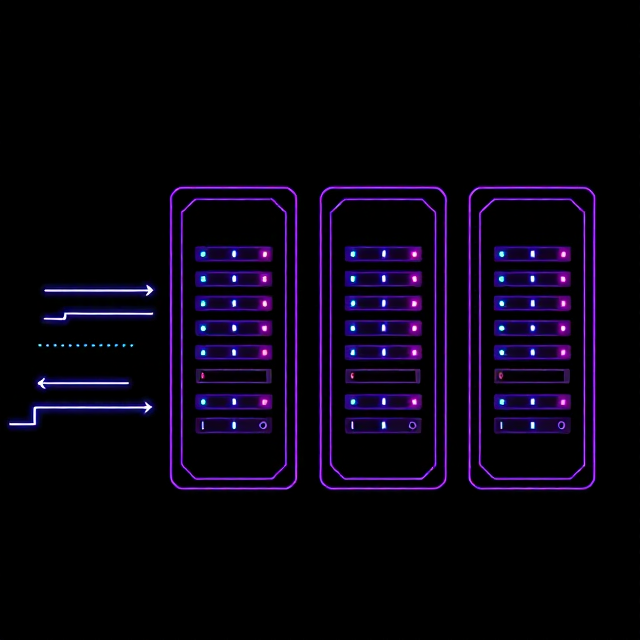
It leaves your computer, and you cannot see where it lands.
Inmost
The audio is decoded on your own chip and dropped. It never crosses the internet, so there is no copy in transit and no vendor log to request.
Your voice never leaves the machine.
The first thing it does is measure itself against you.
Every dictation app ships one default model and hopes it fits your accent, your microphone, and your room. Inmost ships the measurement instead.
Setup asks you to read twenty short prompts out loud. Thirty seconds, one take, no account. Every model on the machine is scored on your speech, and the lowest word error rate wins. Swap microphones, move to a quieter room, or install a newer model, and you can run it again and watch the ranking change.
-
Install and grant two permissions
Microphone, and accessibility so Inmost can paste into the app you are already in.
-
Read twenty prompts out loud
Normal sentences, read normally. This is the only recording that is kept long enough to score, and it never leaves the machine.
-
Hold your key and talk
Text appears where the cursor is. Release, and it is pasted. One undo takes the whole thing back out.
One pack. Measured on your voice, not ours.
Inmost ships a model pack, not one fixed engine: Parakeet, Whisper, Qwen3-ASR, Voxtral, Moonshine, Nemotron, and tiny models small enough to run anywhere. The table below is the sample we have measured so far, on one voice in one room.
| Model | Word error rate | Speed | Size |
|---|---|---|---|
| Qwen3-ASR 1.7B | 5.8% | 25× real time | 2.0 GB |
| Parakeet Unified 0.6B | 6.5% | 100× real time | 614 MB |
| Parakeet TDT v3 | 7.1% | 71× real time | 480 MB |
| Apple Dictation | 12.8% | 31× real time | built in |
How to read it. Word error rate is the share of words the model got wrong, so lower is better. Speed is how much audio it transcribes per second of work: at 100×, an hour of speech becomes text in about 36 seconds.
The trade is the point. The most accurate row here is also the largest download and the slowest of the three local models. Which side of that trade you want depends on your voice and your patience, and it is exactly the question setup answers for you.
And the honest part. A cloud model with far more parameters will beat all four of these numbers. We are not claiming otherwise. Inmost competes on where the audio goes, how fast the text appears, and paying once.
$39, once, and then it is yours.
No subscription, no cap on how much you dictate, no per-word billing, and no renewal date. Buy it, run the setup test, and use the model that wins on your voice.
- Speech recognition that runs entirely on this Mac
- Every installed model scored against your own recording
- Your own vocabulary list for names, acronyms, and jargon
- Menu bar app, launch at login, hold to talk or tap to toggle
- Text pasted at the cursor, removed in one undo
- Updates that do not make you re-grant microphone access
30 days to change your mind. Email us, we refund the $39, no form and no exit interview.
- Requires
- macOS 14+
- Chip
- Apple Silicon
- Account
- none
- Telemetry
- none
What people ask before buying.
-
Is it accurate enough to actually use?
Usually, and you get to check before you decide. On our test voice the best local models land between 5.8% and 7.1% word error rate, which is roughly one word in fifteen. In practice that means a name or a number to fix now and then, not a paragraph to rewrite.
Accuracy moves with your accent, your microphone, and your room, which is why the app measures instead of promising. Cloud services still win on raw word error rate. If you need the lowest error rate on earth and do not care where the audio goes, use one of those. If you need the words to stay here, this is the trade.
-
Why not just use the free dictation built into macOS?
For a short message, you can. It has gotten better, and some of it now runs offline. Three things it will not do: it gives you no choice of model and no score against your own voice, so you cannot tell whether it is mishearing you because of your accent, your mic, or the room. It has no vocabulary list for the names and jargon your work is full of. And on the same test voice, Apple Dictation scored 12.8% against 5.8% to 7.1% for the local models in the table above, so more than twice as much cleanup.
Those numbers are on one voice, in one room, and yours will differ. That is the argument for measuring, not against Apple.
-
Does it work on Windows?
No. Inmost is a Mac app: macOS 14 or later, Apple Silicon only. Windows needs a different capture layer, a different way of getting text into other apps, and its own signing and installer work, so it is a second product rather than a port. We would rather ship one platform that works than two that half work, and we are not going to pretend a port is around the corner.
No Windows build exists today, and there is no date to give you. When there is one, it will be on this page first.
-
What happens to my audio?
It is decoded on the Mac, in memory, and dropped once the text is inserted. It is not uploaded, because there is no server to upload it to and no account to file it under. Nothing leaves the machine: no audio, no transcripts, no usage counts, no crash logs carrying your speech.
The only thing that persists is the transcript text, in a local file you can search, cap by retention, or switch off completely. The first-run recording used for scoring stays on disk only as long as it takes to score the models.
-
Can I get a refund?
Yes. Email hello@inmost.app within 30 days of buying and we refund the $39. No form, no exit interview, no argument about whether you configured it correctly. If the model that won on your Mac was not good enough, that is our problem, not yours.
If you do tell us which model lost and what you were dictating, we read those. It is the most useful feedback the product gets.